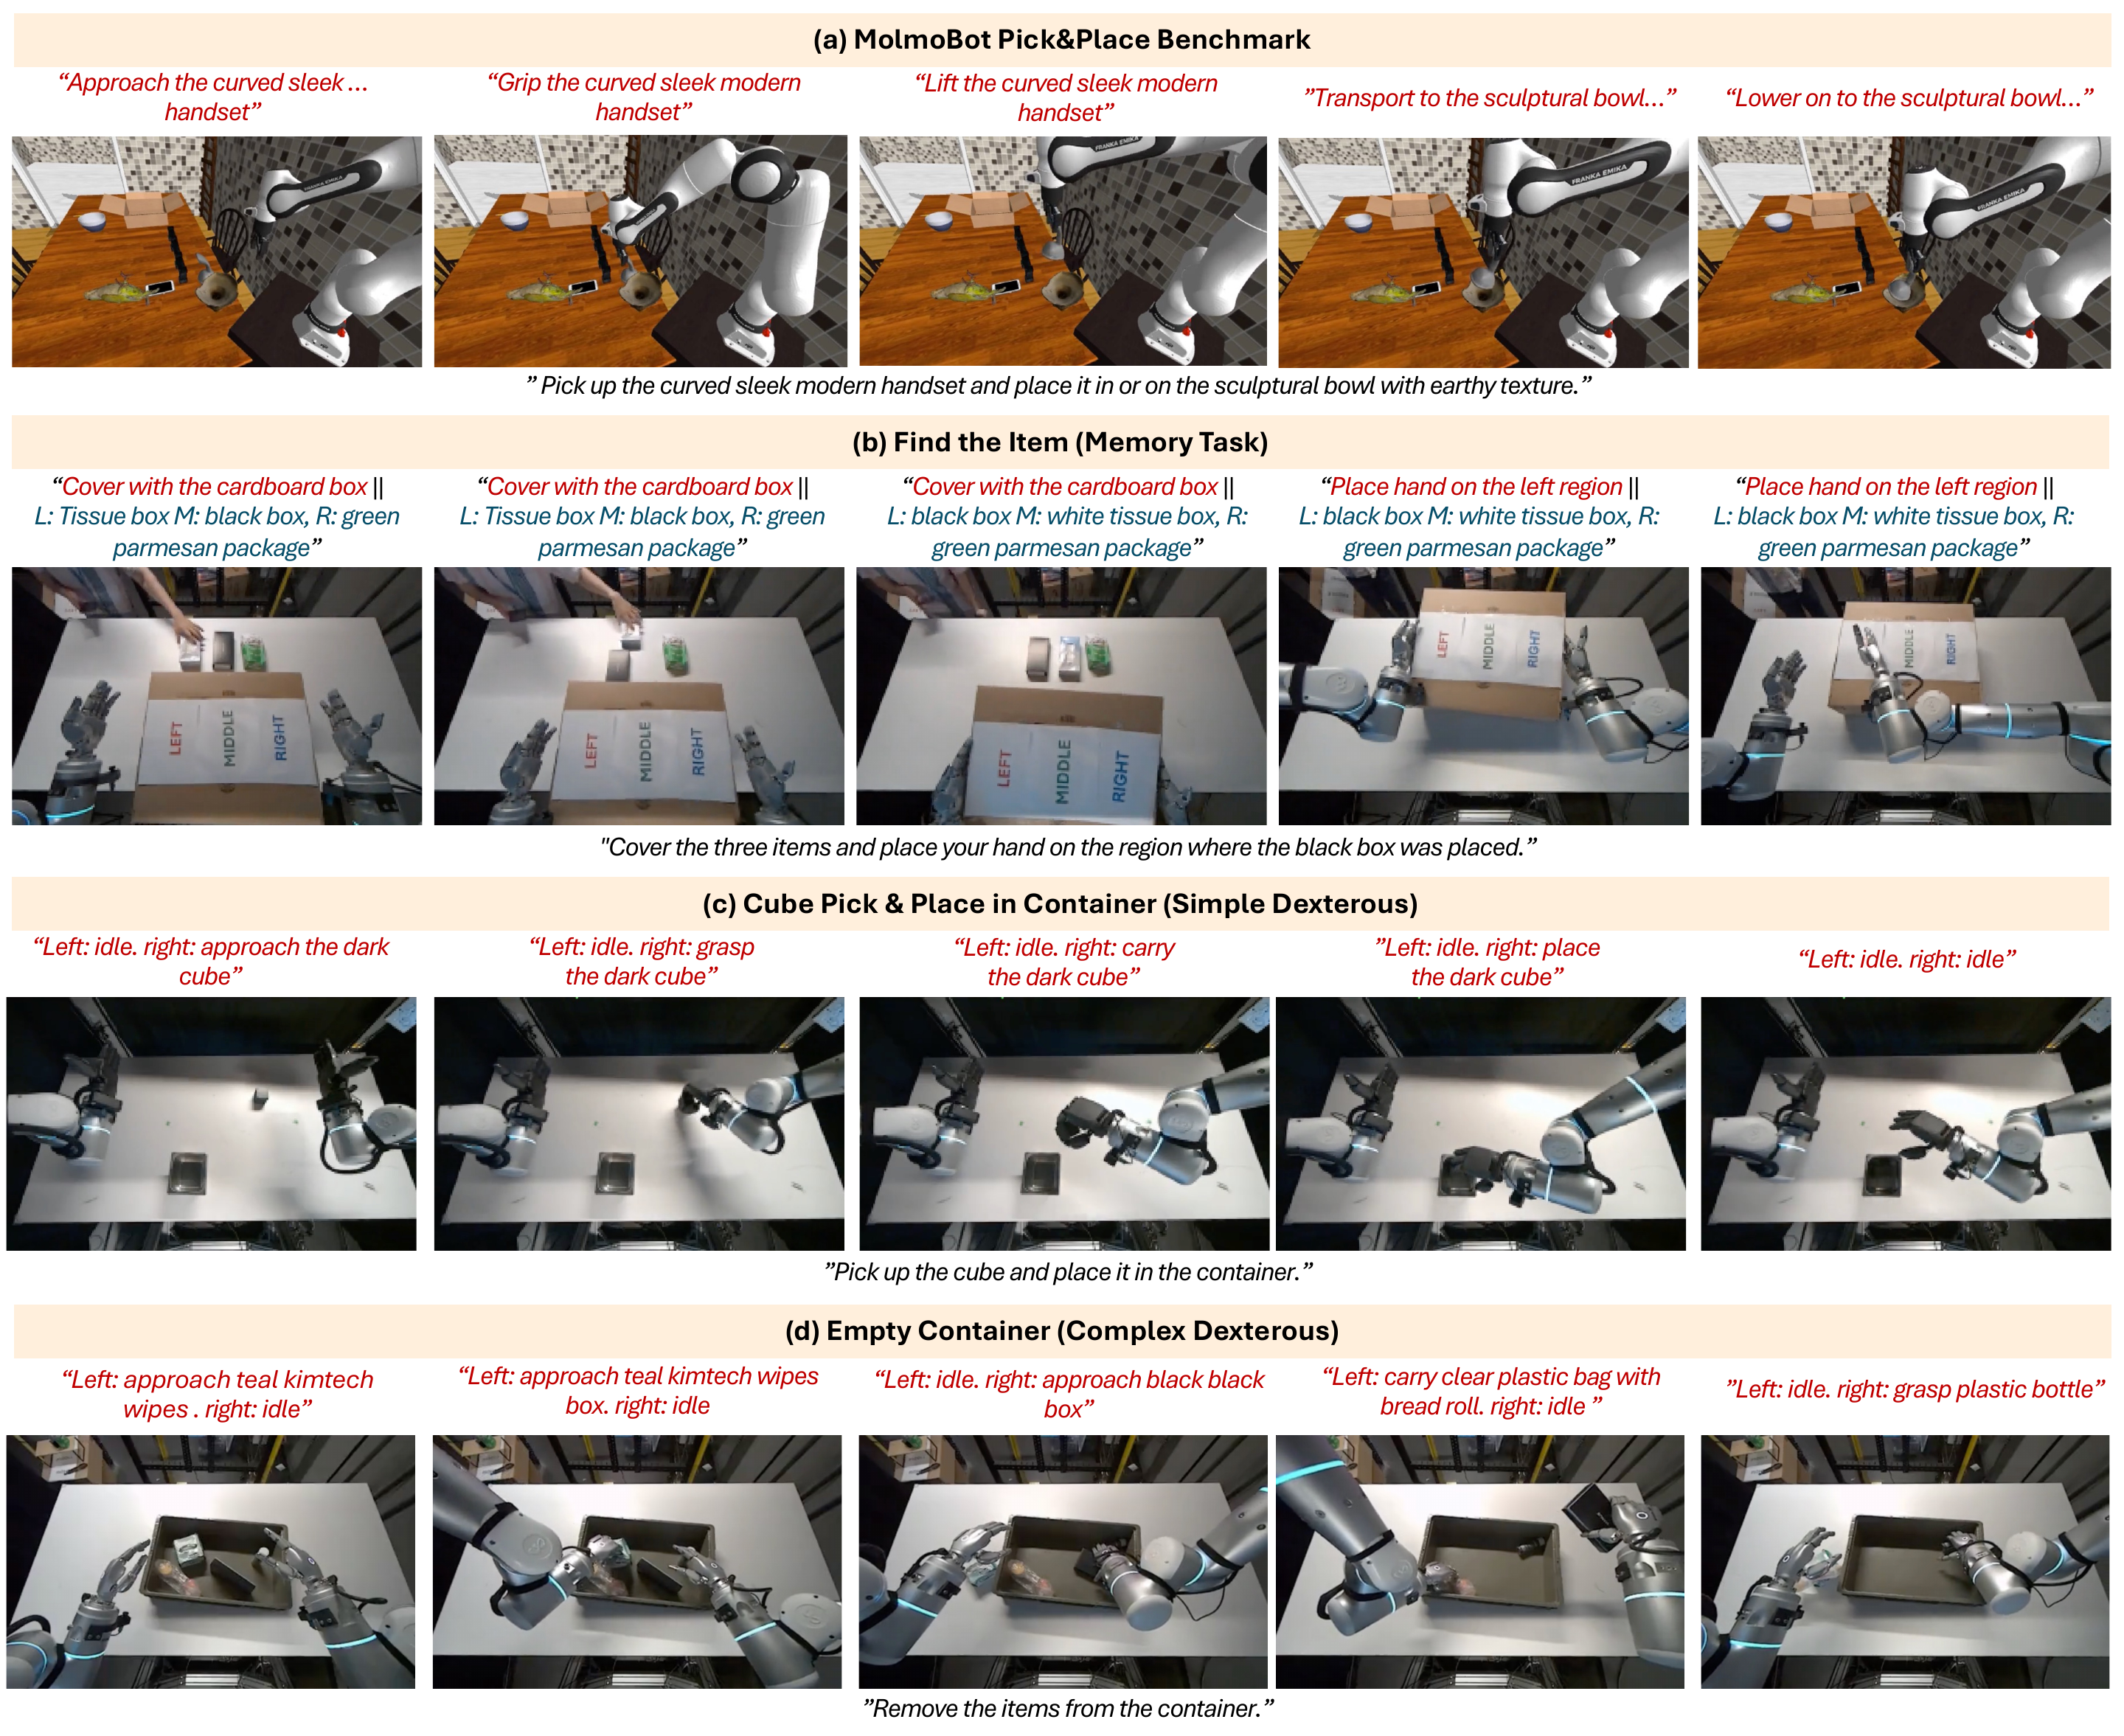
UniWALM: A Unified World-Action-Language Model for Embodied Robot Control
Rahul Sajnani, Diego Romeres, Mingyuan Zhang, Kai Gao, Carl Qi, Baichuan Huang, Srinath Sridhar, Dylan Randle, Lillian J. Ratliff, Jose Barreiros, Manikantan Nambi, and Jeroen Vanbaar
LEAP Workshop @ CoRL 2026; Under Review, 2027
Mixture-of-Transformers (Wan2.2 video + action DiT + discrete-diffusion language expert) co-generates video, action, and language in one parallel diffusion pass.
Policy re-reads its own generated language as memory on every control step — no external VLM / planner.
Real-world memory-dependent manipulation: 11.1% → 61.1% vs same-backbone FastWAM.
34.5% on RMBench, above Mem-0’s privileged-keyframe setup (28.5%).
A mixture-of-transformers (Wan2.2 video backbone + action DiT + discrete-diffusion language expert) co-generates future video, robot action, and a short natural-language memory in a single parallel diffusion pass; the policy re-reads the memory on every control step. 11.1% to 61.1% on real-world memory-dependent manipulation vs same-backbone FastWAM; 34.5% on RMBench, beating Mem-0’s privileged-keyframe setup (28.5%).
@article{sajnani2026uniwalm,title={UniWALM: A Unified World-Action-Language Model for Embodied Robot Control},author={Sajnani, Rahul and Romeres, Diego and Zhang, Mingyuan and Gao, Kai and Qi, Carl and Huang, Baichuan and Sridhar, Srinath and Randle, Dylan and Ratliff, Lillian J. and Barreiros, Jose and Nambi, Manikantan and Vanbaar, Jeroen},year={2027},journal={LEAP Workshop @ CoRL 2026; Under Review},url={https://arxiv.org/abs/2610.28626},webpage={/projects/uniwalm/},note={<ul class="tldr"><li>Mixture-of-Transformers (Wan2.2 video + action DiT + <b>discrete-diffusion language expert</b>) co-generates video, action, and language in <b>one parallel diffusion pass</b>.</li><li>Policy re-reads its own generated language as <b>memory</b> on every control step — no external VLM / planner.</li><li>Real-world memory-dependent manipulation: <b>11.1% → 61.1%</b> vs same-backbone FastWAM.</li><li><b>34.5%</b> on RMBench, above Mem-0's privileged-keyframe setup (28.5%).</li></ul>}}
AppearancePointers: Fine-Grained Multi-Region Control with Appearance Pointers
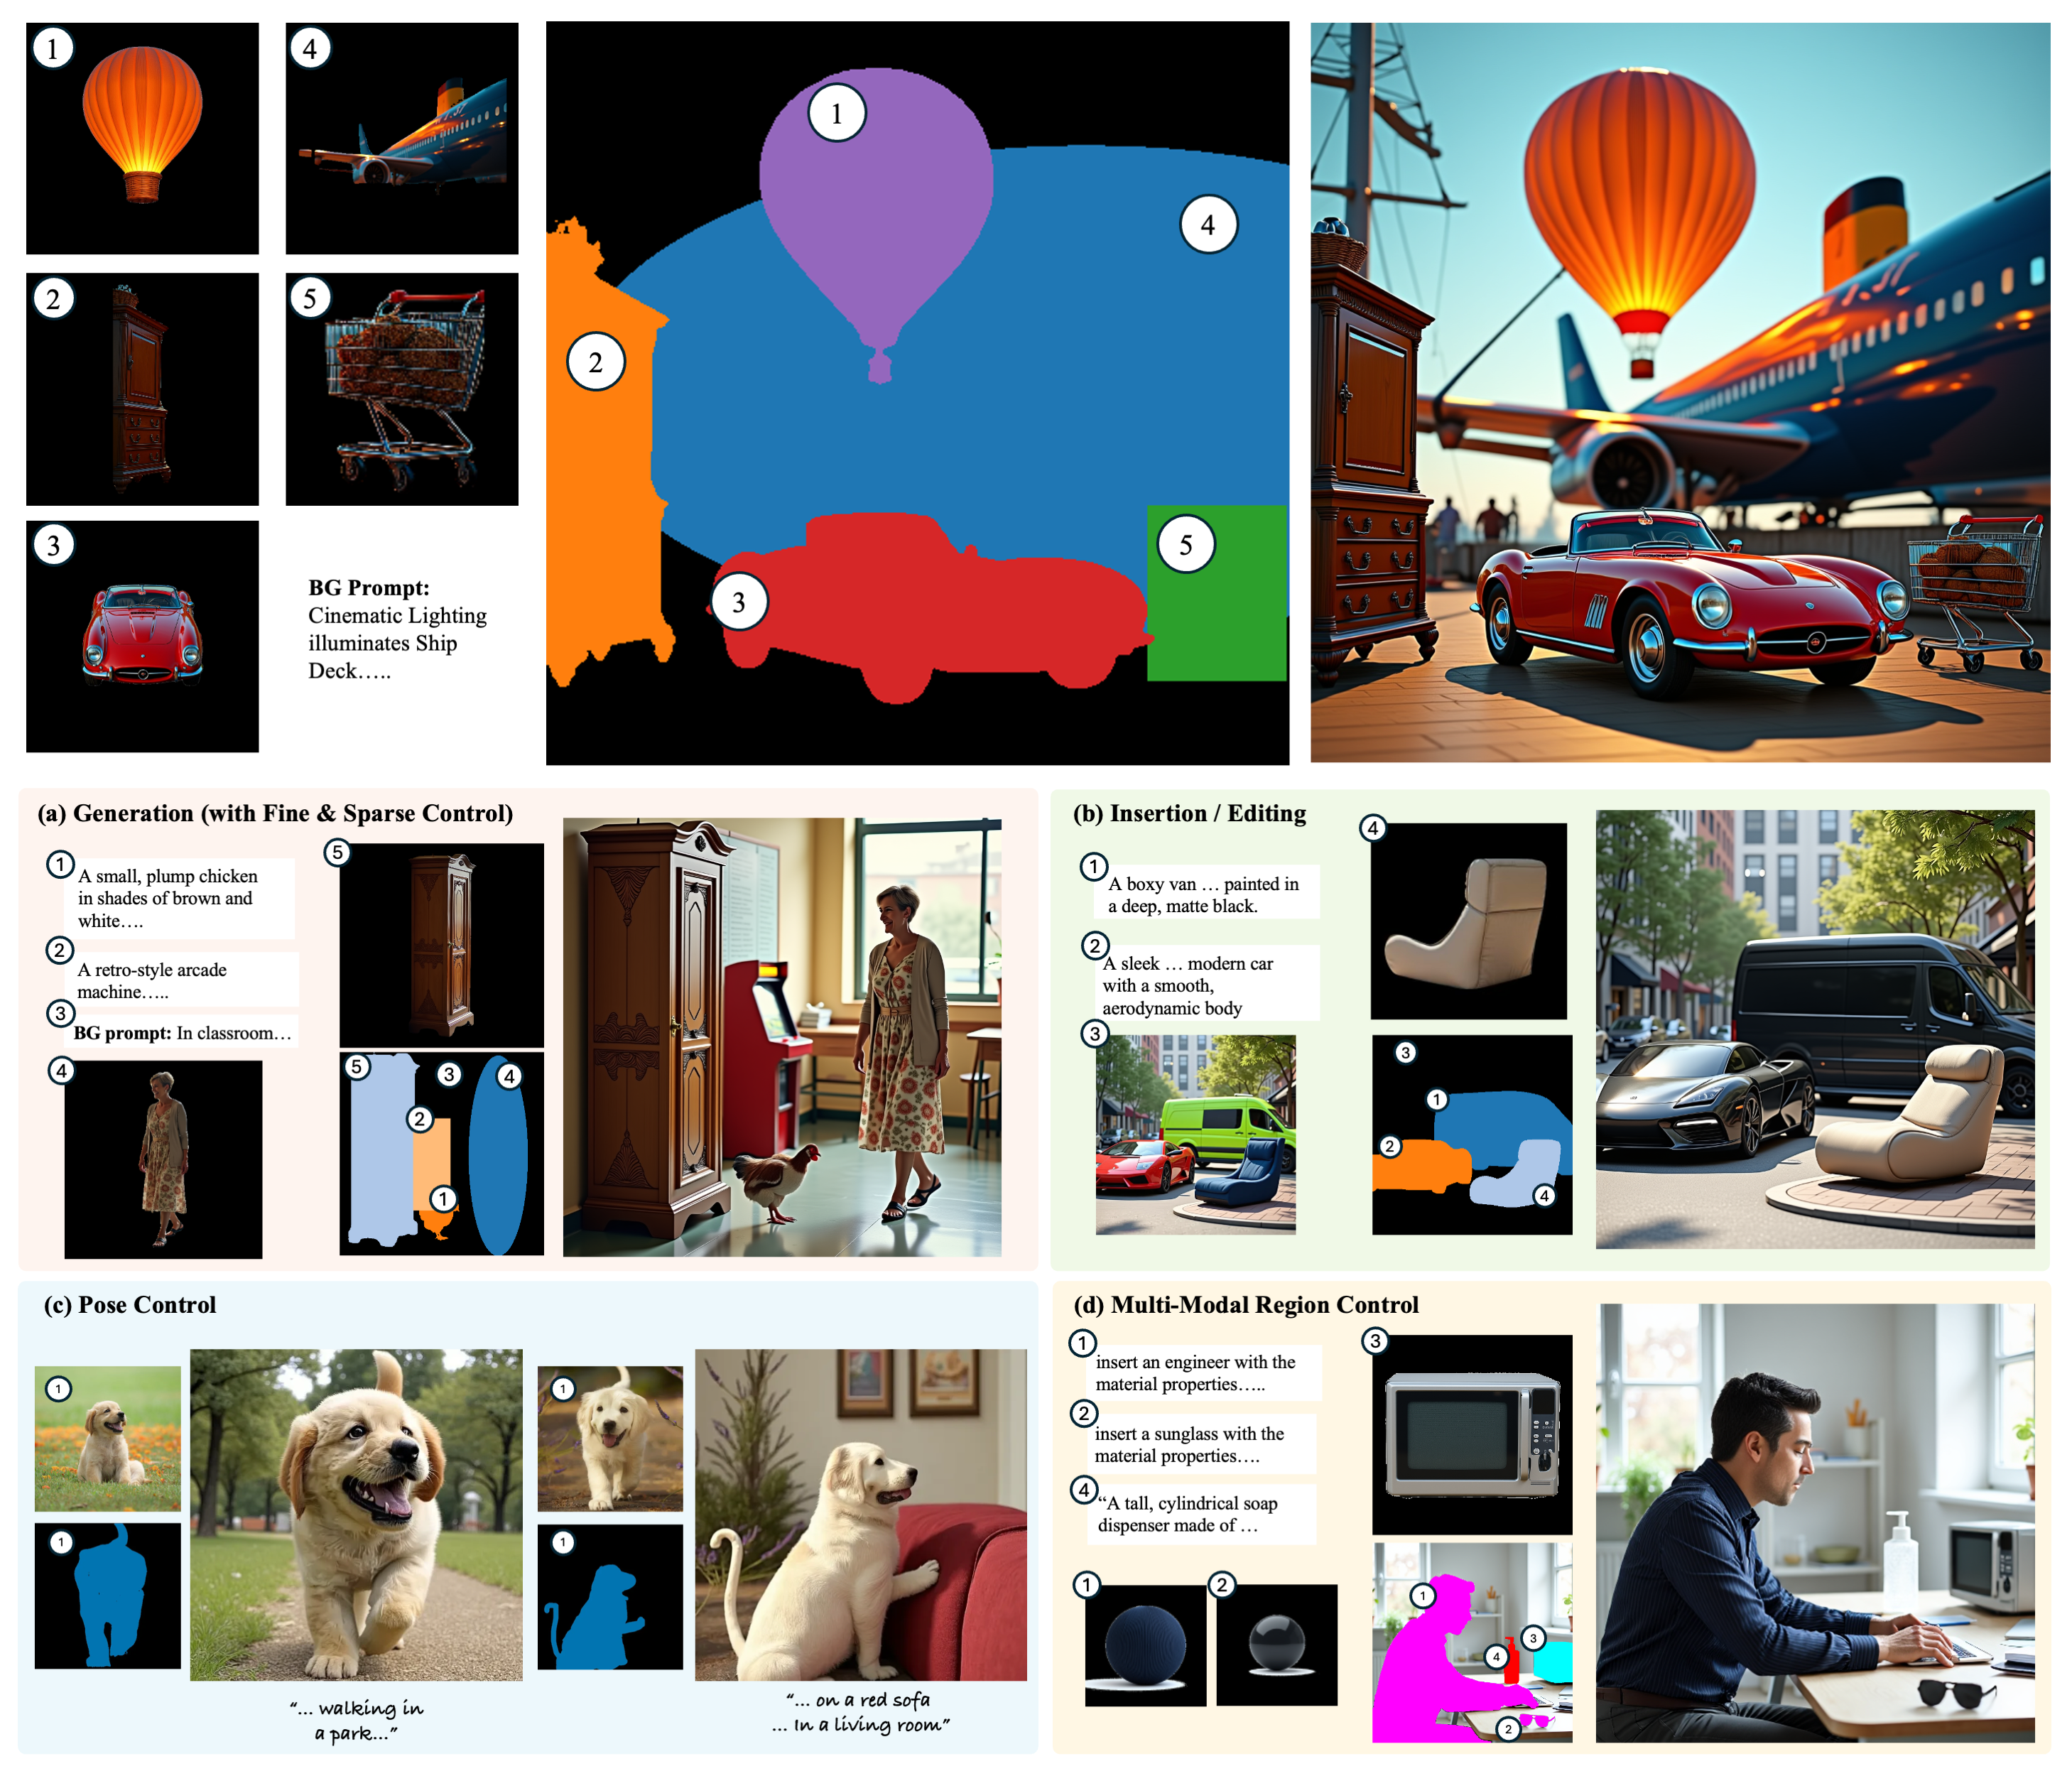
FLUX-based model for multi-region controllable generation: each output region independently steered by text, reference image, and material texture in a single denoising pass.
State-of-the-art on three multi-region fidelity metrics, beating DreamRenderer and MSDiffusion at larger scale.
FLUX-based model for multimodal region control: each output region is independently steered by any mix of text, reference image, and material texture in a single denoising pass. State-of-the-art on three multi-region fidelity metrics; introduces the curated AP-37K multimodal dataset.
@article{sajnani2026appearancepointers,title={AppearancePointers: Fine-Grained Multi-Region Control with Appearance Pointers},author={Sajnani, Rahul and Gadelha, Matheus and Gryaditskaya, Yulia and Sridhar, Srinath and Mech, Radom\'{i}r},year={2027},journal={Under Review},url={https://arxiv.org/abs/2607.19344},webpage={/projects/appearance_pointers/},note={<ul class="tldr"><li>FLUX-based model for <b>multi-region controllable generation</b>: each output region independently steered by text, reference image, and material texture in a single denoising pass.</li><li><b>State-of-the-art</b> on three multi-region fidelity metrics, beating DreamRenderer and MSDiffusion at larger scale.</li><li>Introduces the curated <b>AP-37K</b> multimodal dataset.</li></ul>}}
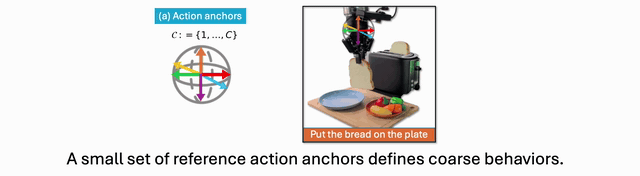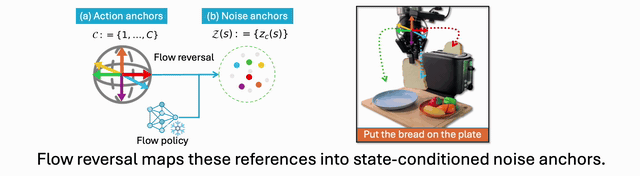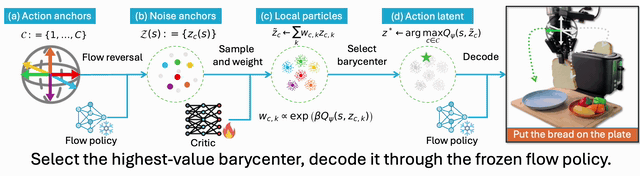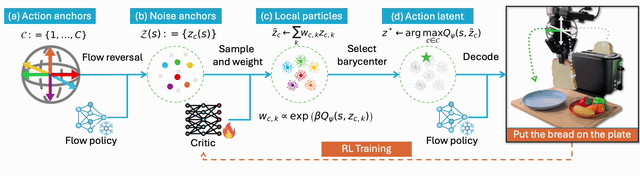
Sample-Efficient Reinforcement Learning for Policy Improvement via Flow-Reversed Action Anchors
Carl Qi, Weijun Dong, Xiaojie Wang, Peiyi Chen, Rahul Sajnani, Mingyuan Zhang, Amy Zhang, Jose Barreiros, Manikantan Nambi, Lillian J. Ratliff, and Dylan Randle
Under Review, 2027
Sample-efficient RL fine-tuning of generalist robot policies using flow-reversed action anchors.
A diffusion-policy improvement scheme that sharply reduces costly online interaction.
Sample-efficient RL fine-tuning of generalist robot policies using flow-reversed action anchors; a diffusion-policy improvement scheme that reduces costly online interaction.
@article{qi2026flowreversed,title={Sample-Efficient Reinforcement Learning for Policy Improvement via Flow-Reversed Action Anchors},author={Qi, Carl and Dong, Weijun and Wang, Xiaojie and Chen, Peiyi and Sajnani, Rahul and Zhang, Mingyuan and Zhang, Amy and Barreiros, Jose and Nambi, Manikantan and Ratliff, Lillian J. and Randle, Dylan},year={2027},journal={Under Review},url={https://arxiv.org/abs/2610.22852},webpage={https://anchorq-rl.com/},note={<ul class="tldr"><li>Sample-efficient <b>RL fine-tuning</b> of generalist robot policies using <b>flow-reversed action anchors</b>.</li><li>A diffusion-policy improvement scheme that sharply reduces costly online interaction.</li></ul>}}
GeoDiffuser: Geometry-Based Image Editing with Diffusion Models
Rahul Sajnani, Jeroen Vanbaar, Jie Min, Kapil Katyal, and Srinath Sridhar
In Proceedings of the IEEE/CVF Winter Conference on Applications of Computer Vision (WACV)(Best Student Paper) , 2025
Training-free geometry-based image editing on a frozen T2I diffusion model.
User specifies a 3D rigid transform (rotate, translate, scale); GeoDiffuser rewrites attention maps to realize it.
No fine-tuning, no 3D supervision — WACV 2025 Best Student Paper.
@inproceedings{sajnani2024geodiffusergeometrybasedimageediting,title={GeoDiffuser: Geometry-Based Image Editing with Diffusion Models},author={Sajnani, Rahul and Vanbaar, Jeroen and Min, Jie and Katyal, Kapil and Sridhar, Srinath},year={2025},booktitle={Proceedings of the IEEE/CVF Winter Conference on Applications of Computer Vision (WACV)},eprint={2404.14403},archiveprefix={arXiv},primaryclass={cs.CV},url={https://arxiv.org/abs/2404.14403},webpage={/projects/geodiffuser/},note={<ul class="tldr"><li><b>Training-free</b> geometry-based image editing on a frozen T2I diffusion model.</li><li>User specifies a <b>3D rigid transform</b> (rotate, translate, scale); GeoDiffuser rewrites attention maps to realize it.</li><li>No fine-tuning, no 3D supervision — WACV 2025 <b>Best Student Paper</b>.</li></ul>}}
GenHSI: Training-Free Controllable Generation of Human-Scene Interaction Videos
Zekun Li, Rui Zhou, Rahul Sajnani, Xiaoyan Cong, Daniel Ritchie, and Srinath Sridhar
In Proceedings of the IEEE/CVF Winter Conference on Applications of Computer Vision (WACV), 2026
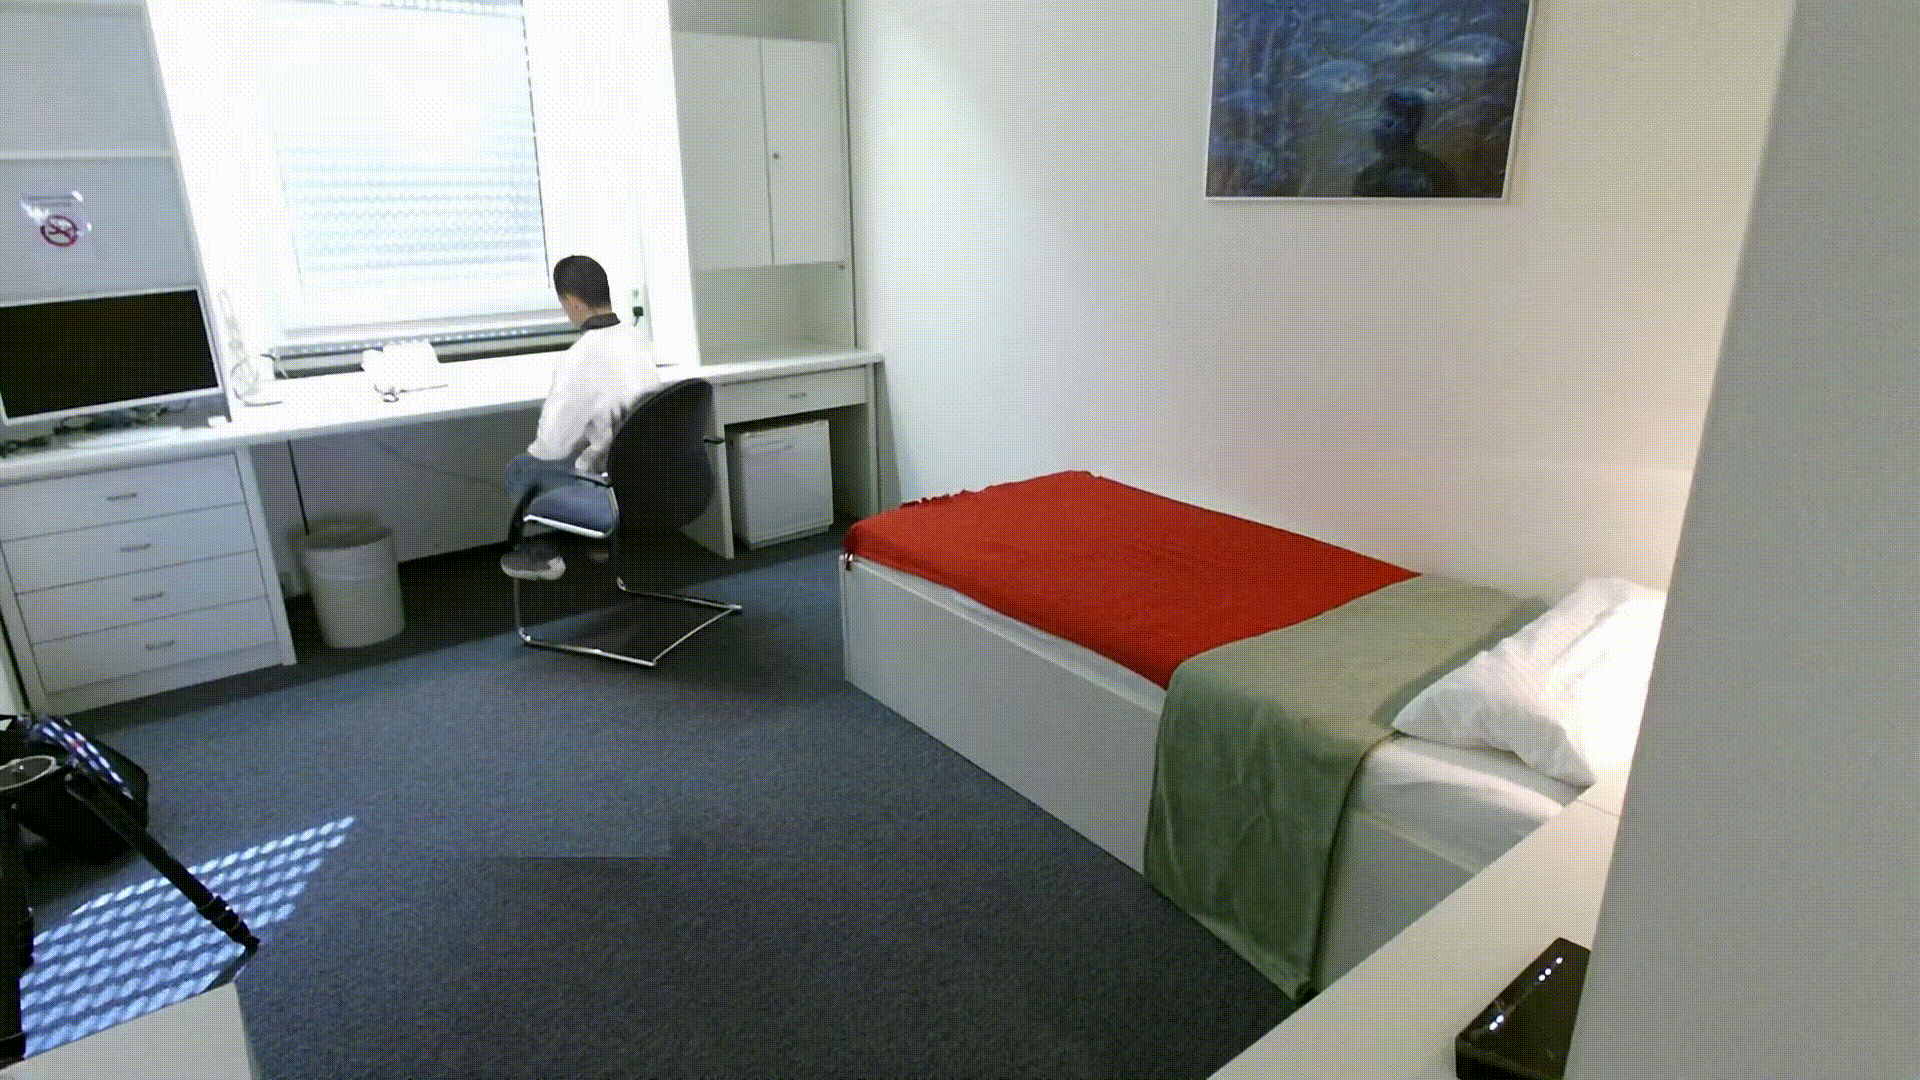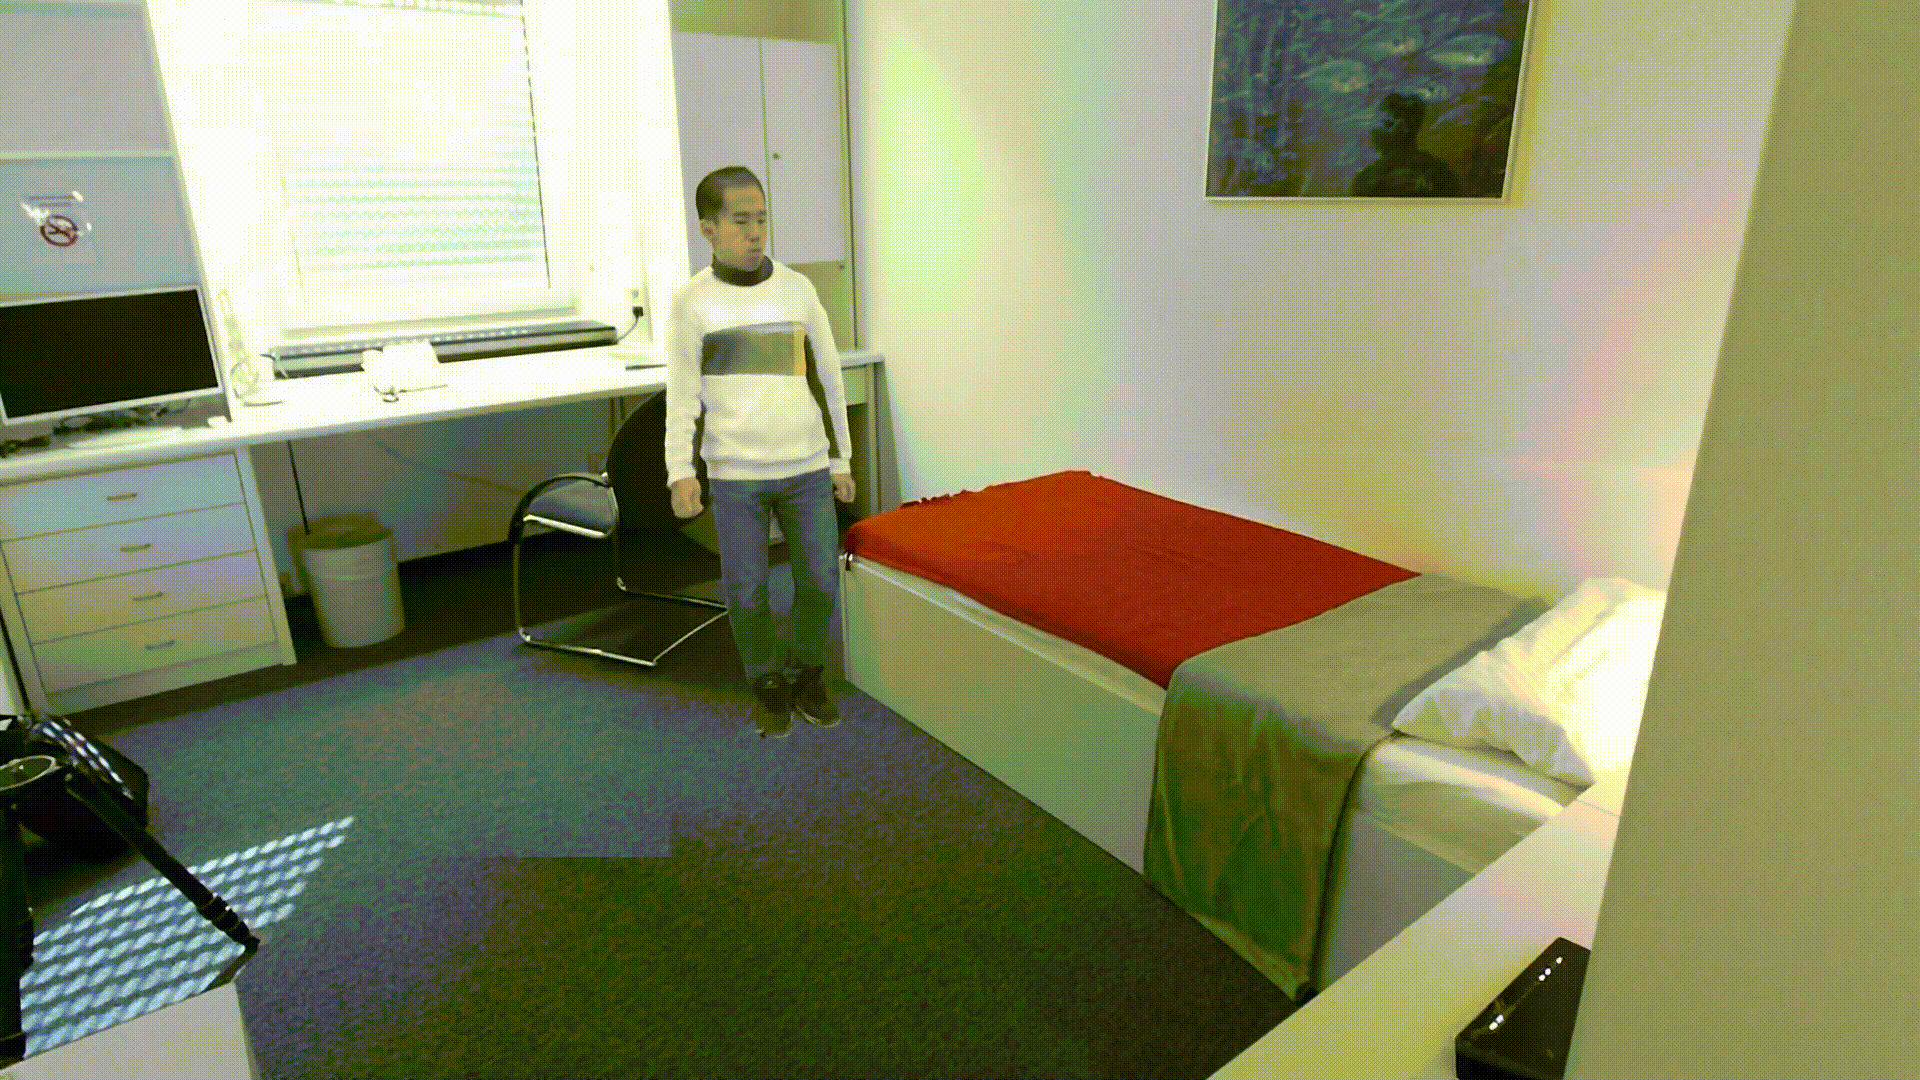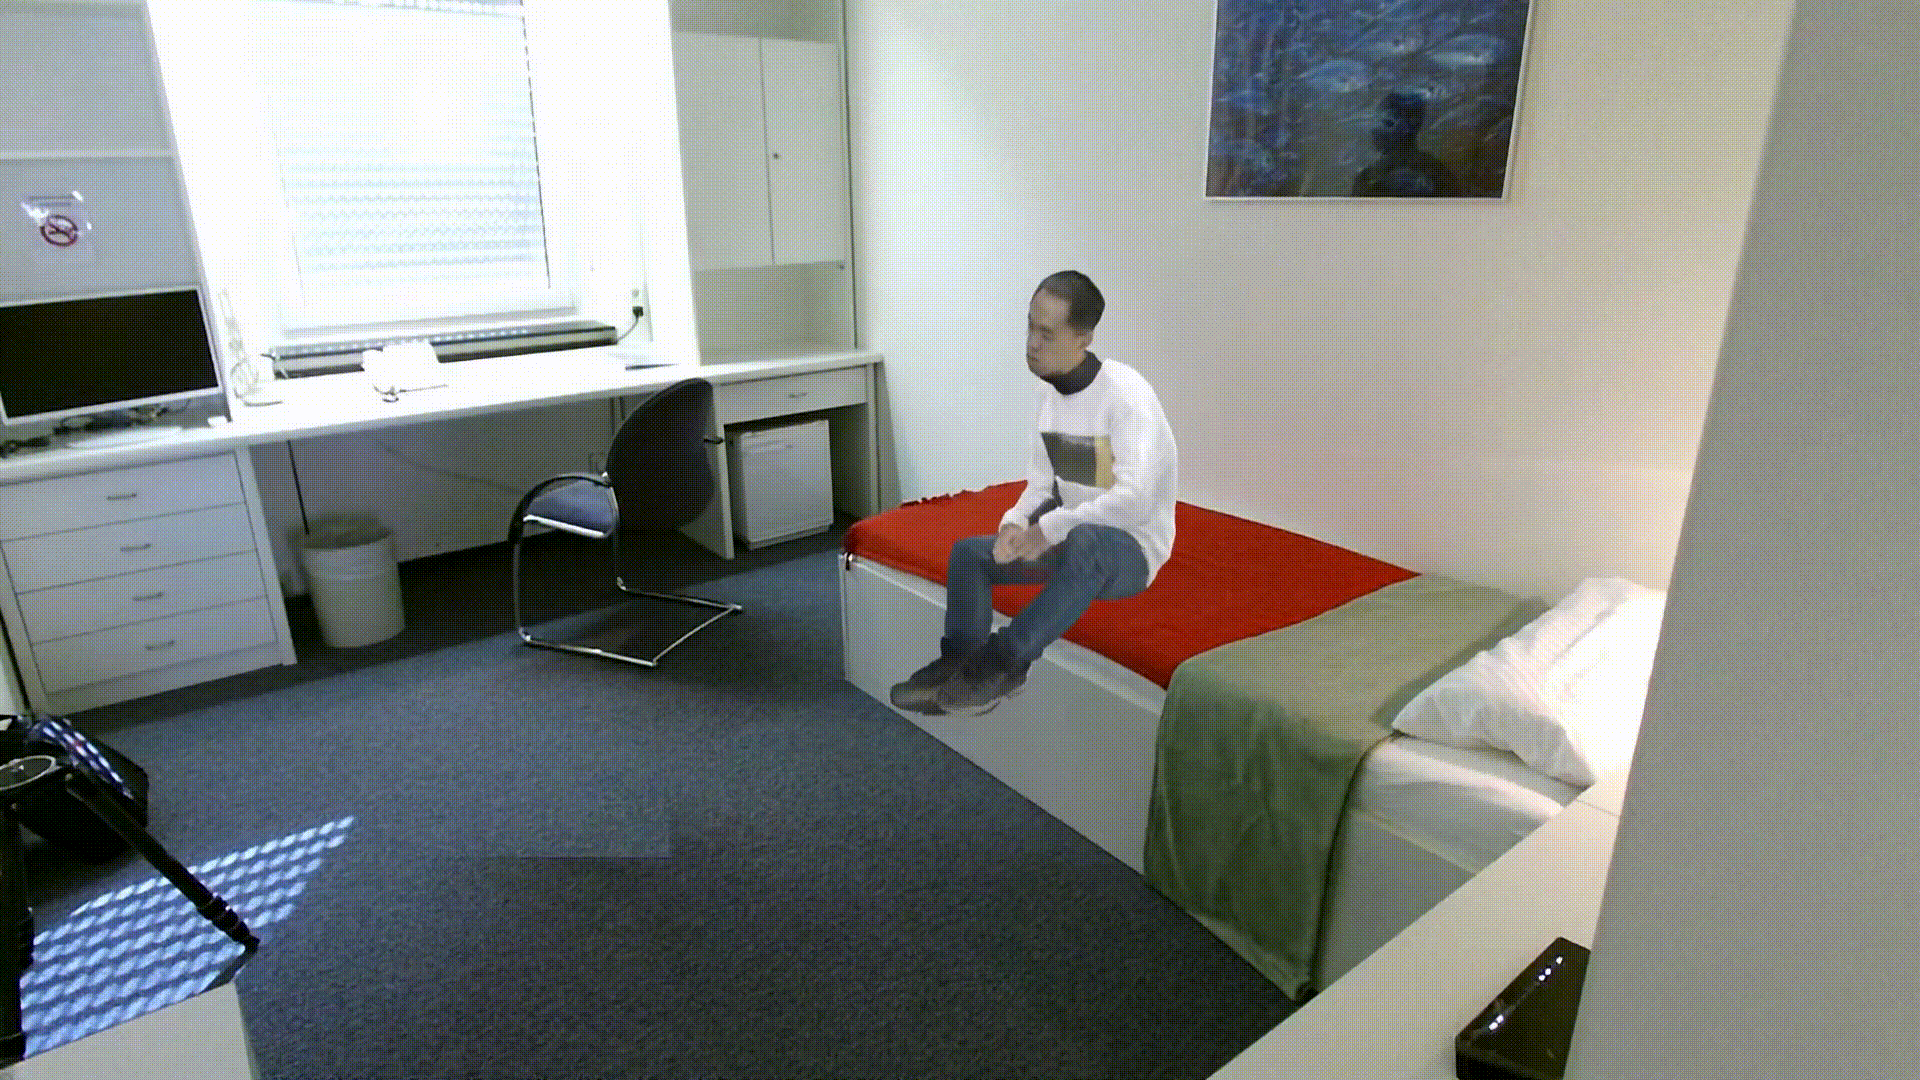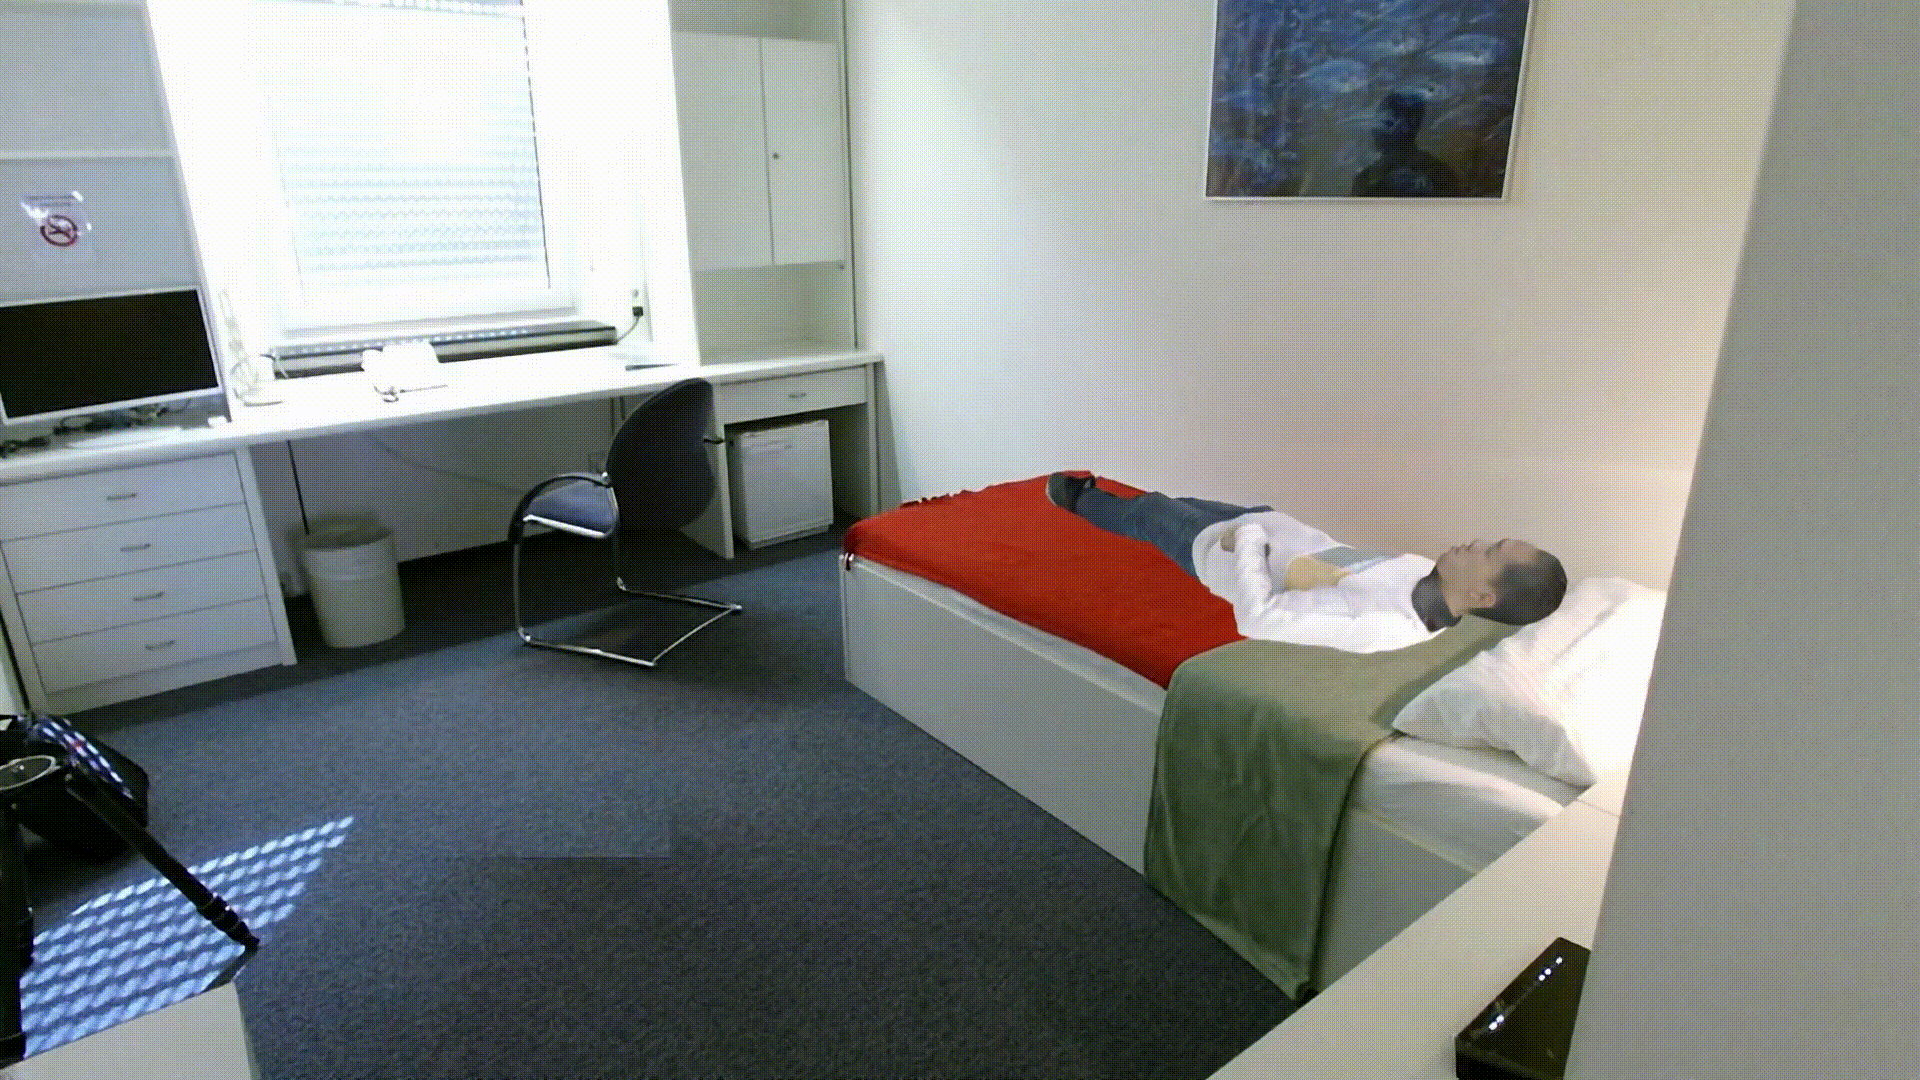
Training-free controllable generation of human–scene interaction videos.
Uses a video-diffusion prior with per-region controls — no retraining for new scenes or humans.
@inproceedings{genhsi2026,title={GenHSI: Training-Free Controllable Generation of Human-Scene Interaction Videos},author={Li, Zekun and Zhou, Rui and Sajnani, Rahul and Cong, Xiaoyan and Ritchie, Daniel and Sridhar, Srinath},year={2026},booktitle={Proceedings of the IEEE/CVF Winter Conference on Applications of Computer Vision (WACV)},webpage={https://kunkun0w0.github.io/project/GenHSI/},note={<ul class="tldr"><li><b>Training-free</b> controllable generation of human–scene interaction videos.</li><li>Uses a video-diffusion prior with per-region controls — no retraining for new scenes or humans.</li></ul>}}
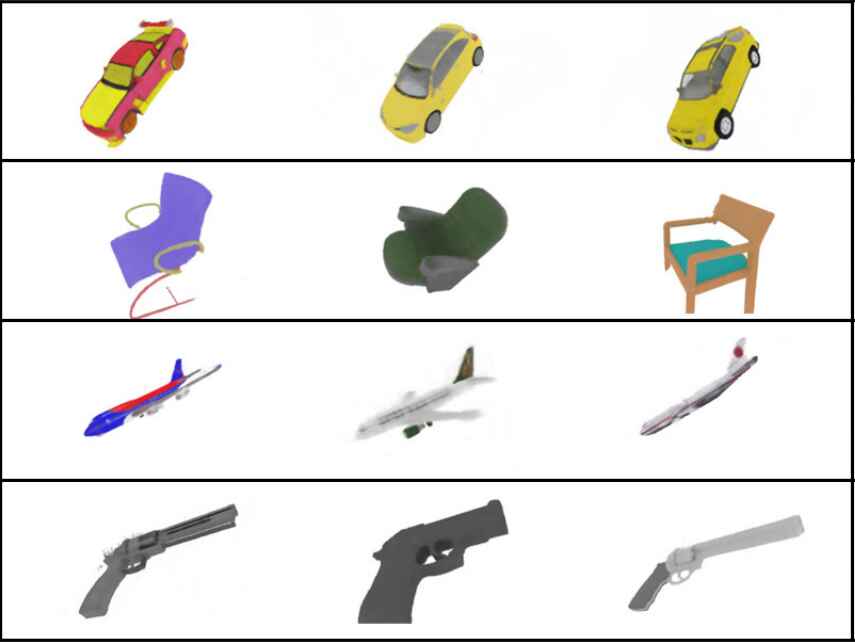
Canonical Fields: Self-Supervised Learning of Pose-Canonicalized Neural Fields
@inproceedings{Agaram_2023_CVPR,author={Agaram, Rohith and Dewan, Shaurya and Sajnani, Rahul and Poulenard, Adrien and Krishna, Madhava and Sridhar, Srinath},title={Canonical Fields: Self-Supervised Learning of Pose-Canonicalized Neural Fields},booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},month=jun,year={2023},pages={4500-4510},webpage={https://ivl.cs.brown.edu/research/canonical-fields.html},note={<ul class="tldr"><li>Self-supervised learning of <b>pose-canonicalized neural fields</b> (NeRFs).</li><li>Discovers a canonical frame for an object category without any pose or 3D supervision.</li><li>CVPR 2023 <b>Highlight</b>.</li></ul>}}
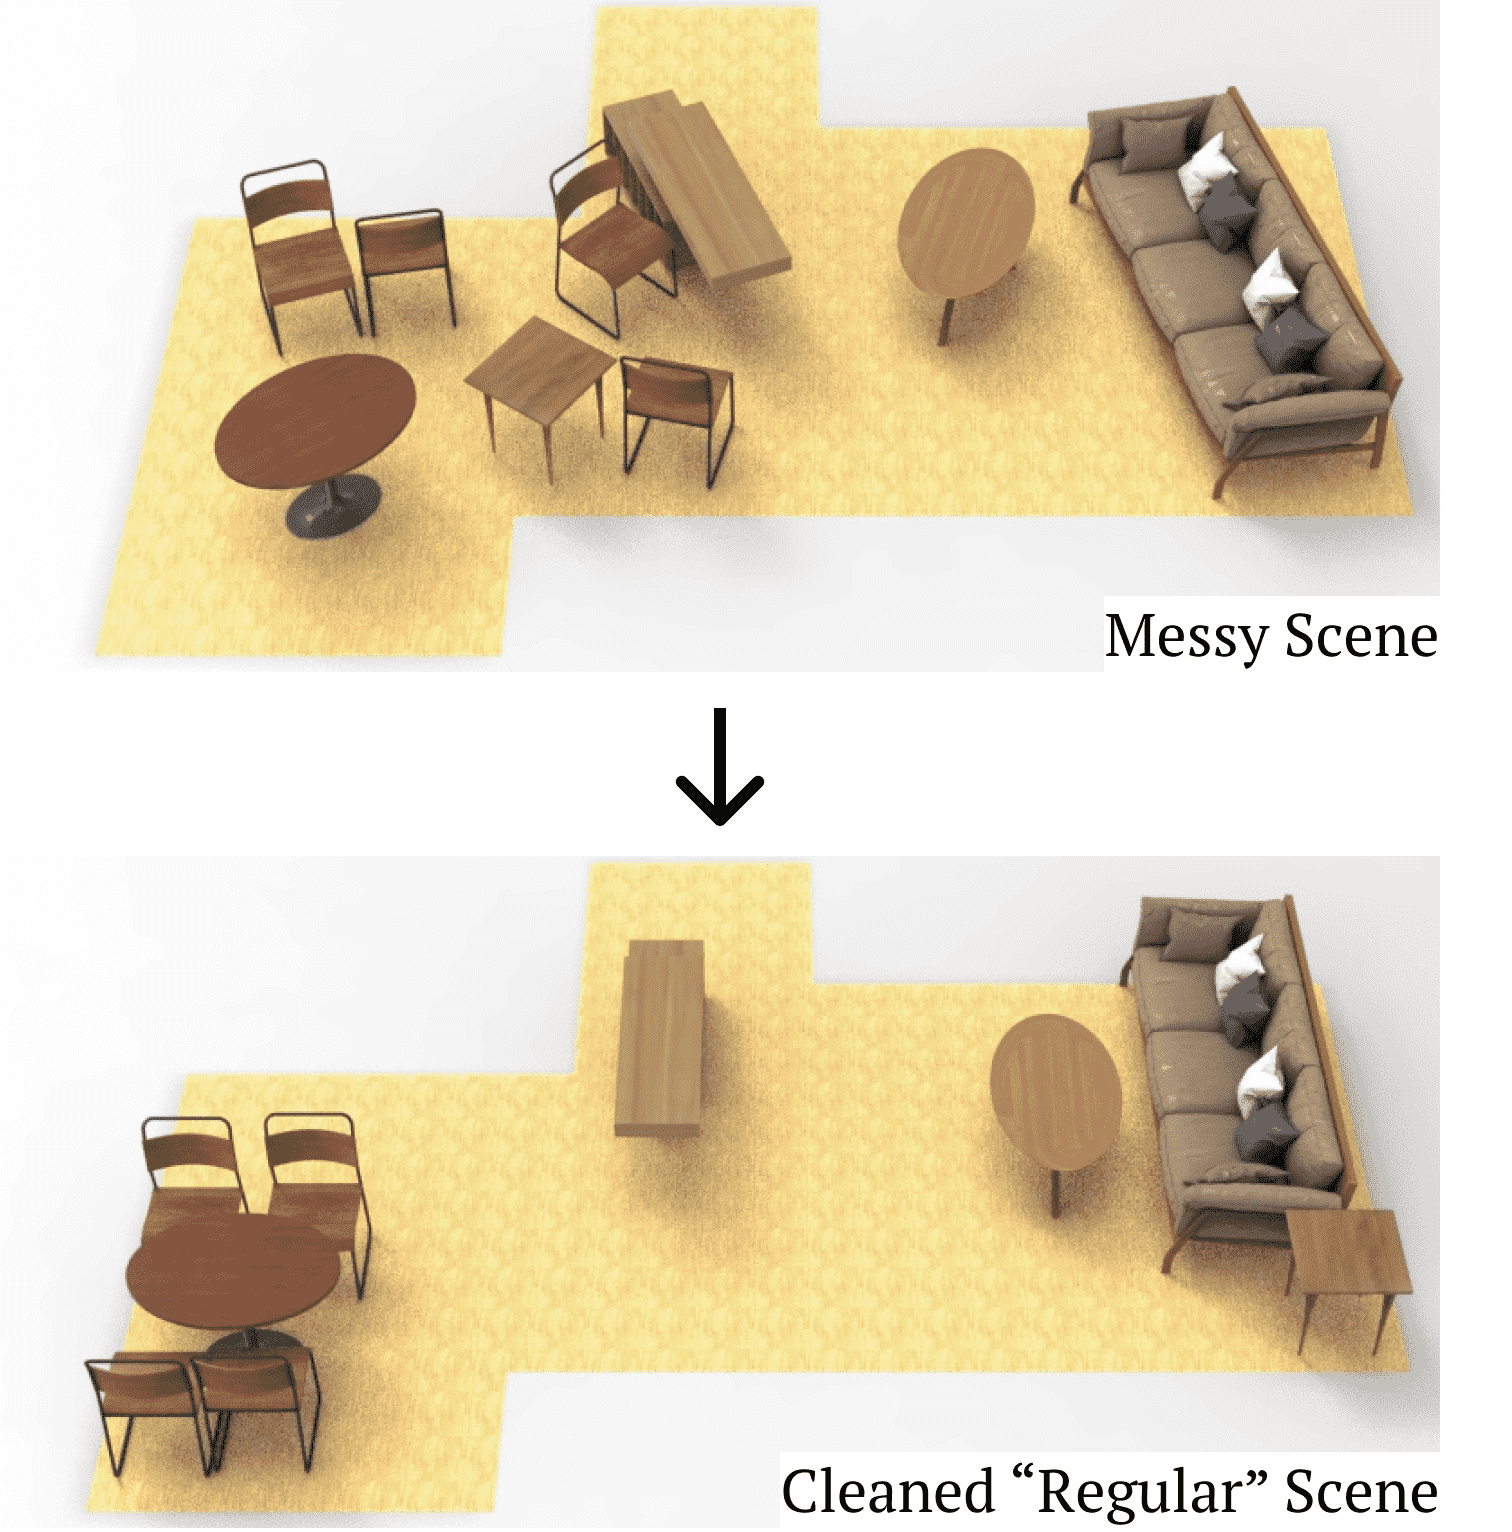
LEGO-Net: Learning Regular Rearrangements of Objects in Rooms
Qiuhong Anna Wei, Sijie Ding, Jeong Joon Park, Rahul Sajnani, Adrien Poulenard, Srinath Sridhar, and Leonidas Guibas
In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Jun 2023
Learns to rearrange cluttered rooms into regular layouts using a diffusion-based scene editor.
Discovers regularity patterns (alignment, symmetry) directly from indoor-scene data.
@inproceedings{Wei_2023_CVPR,author={Wei, Qiuhong Anna and Ding, Sijie and Park, Jeong Joon and Sajnani, Rahul and Poulenard, Adrien and Sridhar, Srinath and Guibas, Leonidas},title={LEGO-Net: Learning Regular Rearrangements of Objects in Rooms},booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},month=jun,year={2023},pages={19037-19047},webpage={https://ivl.cs.brown.edu/research/lego-net.html},note={<ul class="tldr"><li>Learns to <b>rearrange cluttered rooms into regular layouts</b> using a diffusion-based scene editor.</li><li>Discovers regularity patterns (alignment, symmetry) directly from indoor-scene data.</li></ul>}}
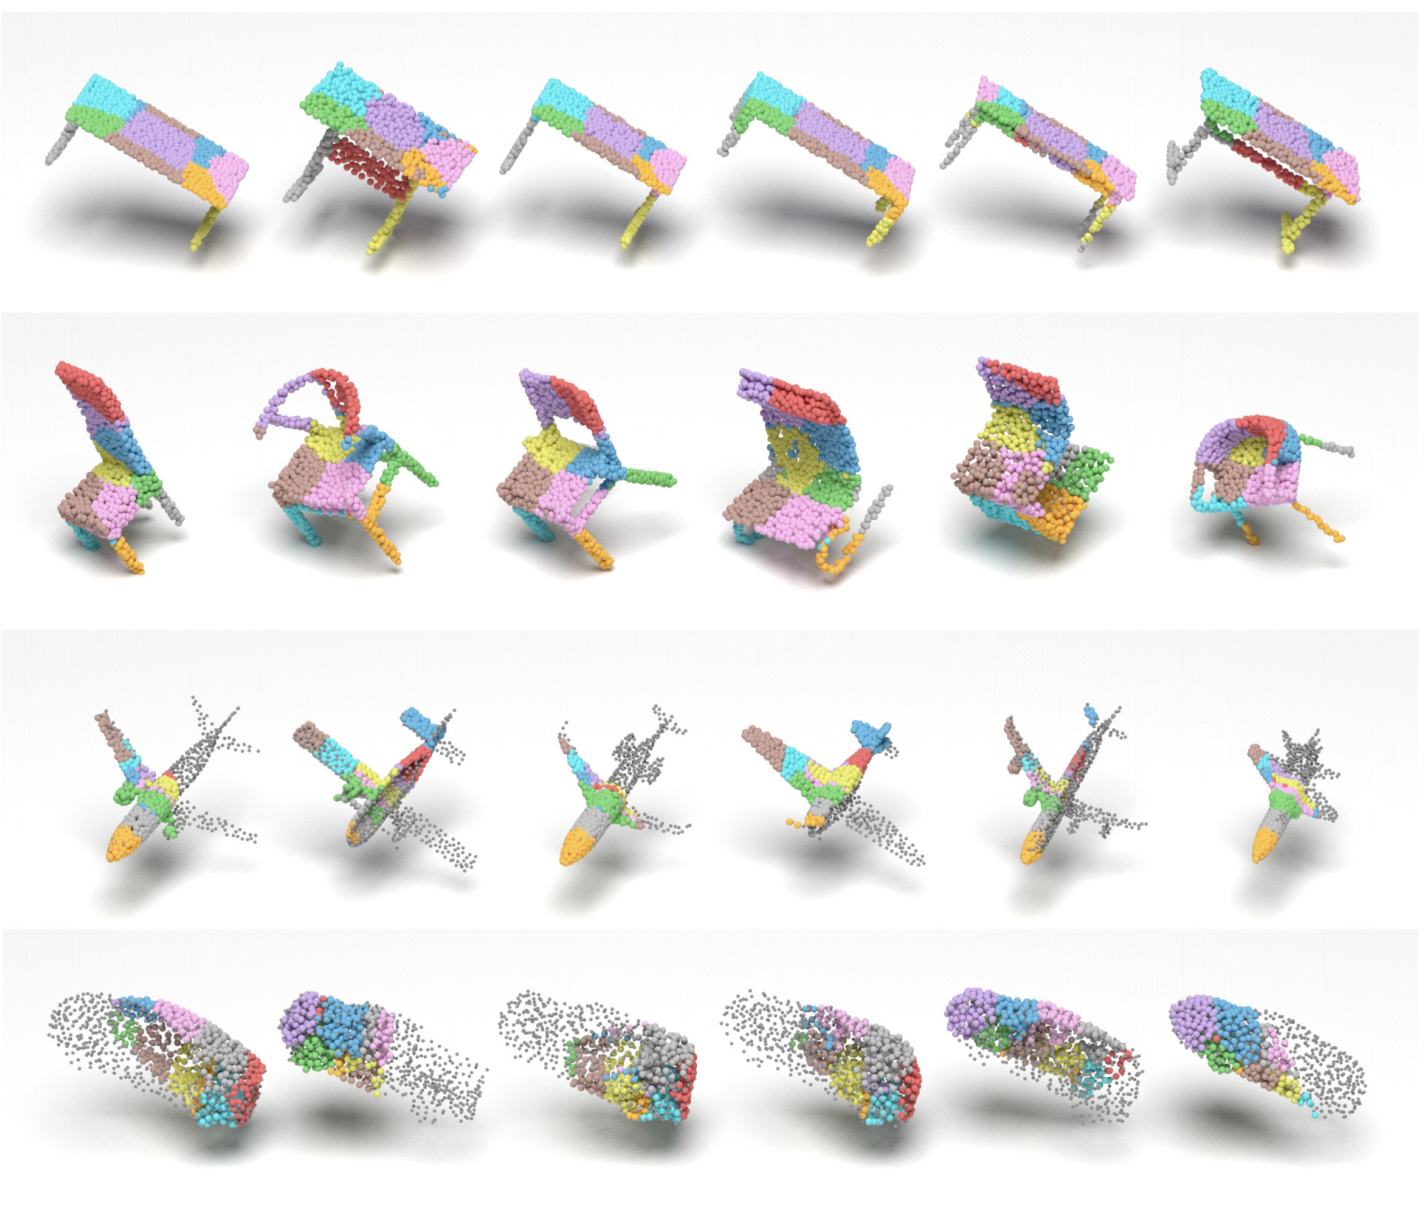
ConDor: Self-Supervised Canonicalization of 3D Pose for Partial Shapes
Rahul Sajnani, Adrien Poulenard, Jivitesh Jain, Radhika Dua, Leonidas J. Guibas, and Srinath Sridhar
In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Jun 2022
SO(3)-equivariant self-supervised 3D pose canonicalization — works on partial point clouds.
Also performs automatic co-part segmentation as a byproduct.
@inproceedings{Sajnani_2022_CVPR,author={Sajnani, Rahul and Poulenard, Adrien and Jain, Jivitesh and Dua, Radhika and Guibas, Leonidas J. and Sridhar, Srinath},title={ConDor: Self-Supervised Canonicalization of 3D Pose for Partial Shapes},booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},month=jun,year={2022},pages={16969-16979},webpage={https://ivl.cs.brown.edu/ConDor/},note={<ul class="tldr"><li><b>SO(3)-equivariant</b> self-supervised 3D pose canonicalization — works on <b>partial</b> point clouds.</li><li>Also performs automatic co-part segmentation as a byproduct.</li></ul>}}
DRACO: Weakly Supervised Dense Reconstruction And Canonicalization of Objects
Rahul Sajnani, AadilMehdi J. Sanchawala, Krishna Murthy Jatavallabhula, Srinath Sridhar, and K. Madhava Krishna
2021 IEEE International Conference on Robotics and Automation (ICRA), Jun 2021
Weakly-supervised dense reconstruction and pose canonicalization of 3D objects.
Learned without any 3D ground-truth supervision — IEEE ICRA 2021.
@article{Sajnani2020DRACOWS,title={DRACO: Weakly Supervised Dense Reconstruction And Canonicalization of Objects},author={Sajnani, Rahul and Sanchawala, AadilMehdi J. and Jatavallabhula, Krishna Murthy and Sridhar, Srinath and Krishna, K. Madhava},journal={2021 IEEE International Conference on Robotics and Automation (ICRA)},year={2021},pages={10302-10309},url={https://api.semanticscholar.org/CorpusID:227161908},note={<ul class="tldr"><li><b>Weakly-supervised</b> dense reconstruction and <b>pose canonicalization</b> of 3D objects.</li><li>Learned without any 3D ground-truth supervision — IEEE ICRA 2021.</li></ul>}}
Multi-object Monocular SLAM for Dynamic Environments
Gokul B. Nair, Swapnil Daga, Rahul Sajnani, Anirudh Ramesh, Junaid Ahmed Ansari, and K. Madhava Krishna
2020 IEEE Intelligent Vehicles Symposium (IV), Jun 2020
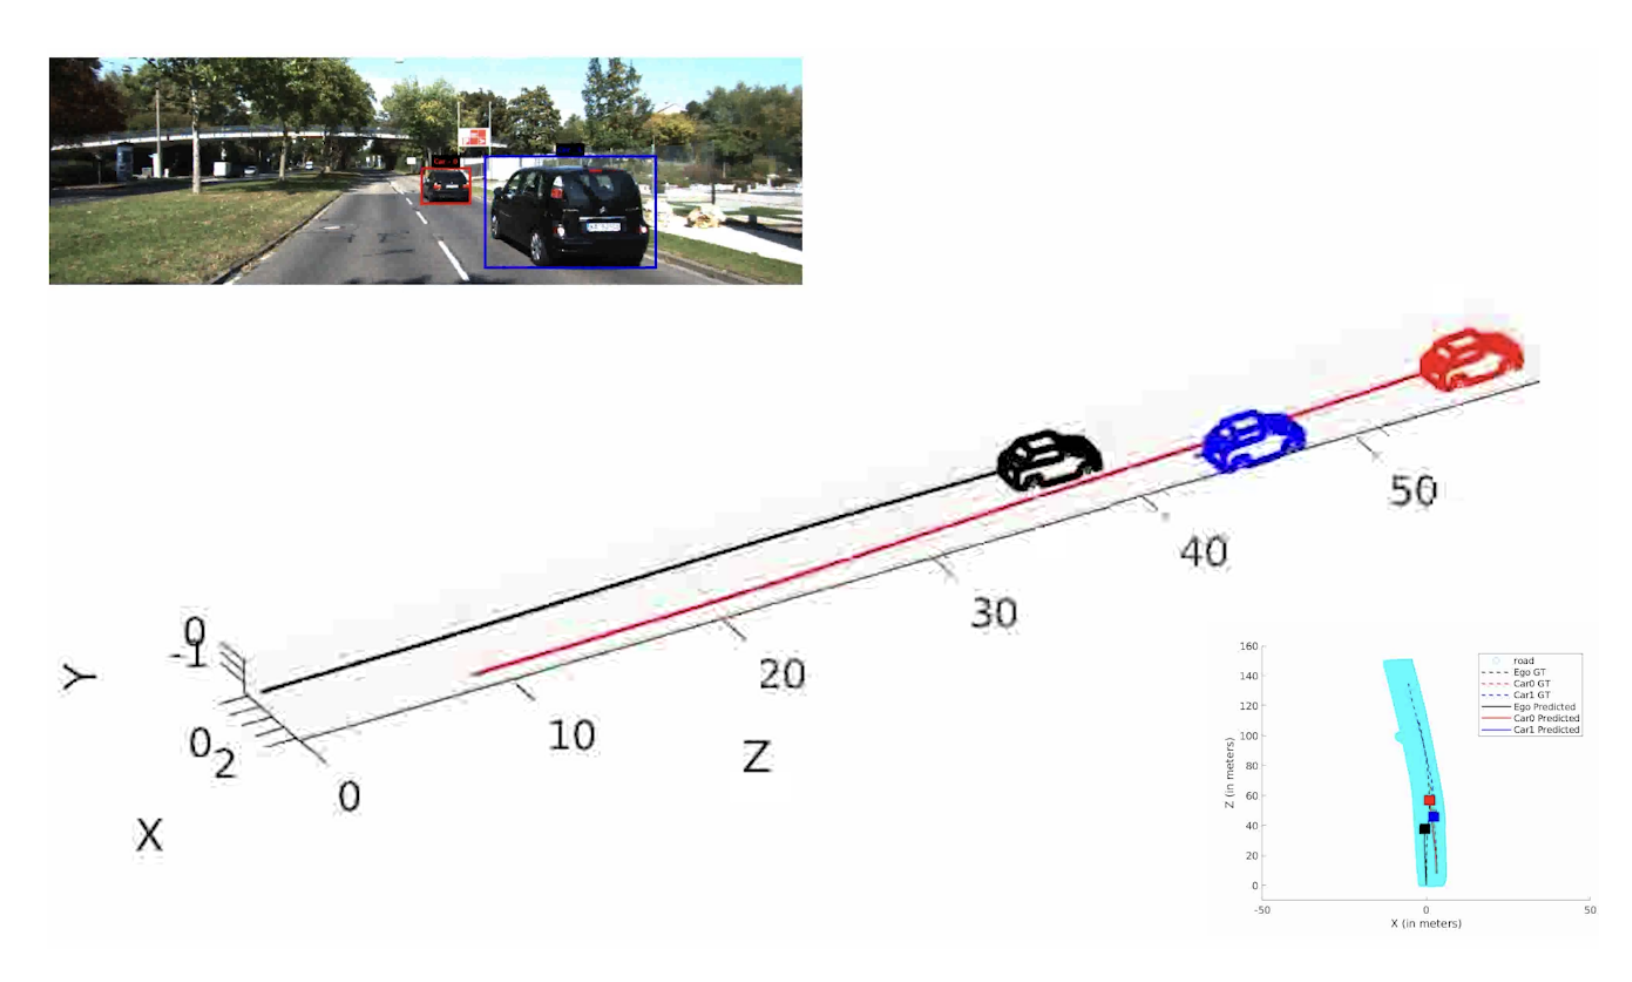
Monocular SLAM that explicitly models independent object motion in dynamic driving scenes.
Handles moving vehicles and pedestrians without filtering them out.
@article{Nair2020MultiobjectMS,title={Multi-object Monocular SLAM for Dynamic Environments},author={Nair, Gokul B. and Daga, Swapnil and Sajnani, Rahul and Ramesh, Anirudh and Ansari, Junaid Ahmed and Krishna, K. Madhava},journal={2020 IEEE Intelligent Vehicles Symposium (IV)},year={2020},pages={651-657},url={https://api.semanticscholar.org/CorpusID:211069692},note={<ul class="tldr"><li>Monocular SLAM that <b>explicitly models independent object motion</b> in dynamic driving scenes.</li><li>Handles moving vehicles and pedestrians without filtering them out.</li></ul>}}
Unlocked: A Game On Human Trafficking
AadilMehdi J Sanchawala, Adhithya Arun, Rahul Sajnani, and Kavita Vemuri
@inproceedings{9231579,author={Sanchawala, AadilMehdi J and Arun, Adhithya and Sajnani, Rahul and Vemuri, Kavita},booktitle={2020 IEEE Conference on Games (CoG)},title={Unlocked: A Game On Human Trafficking},year={2020},volume={},number={},pages={415-422},keywords={Games;Faces;Information technology;Production facilities;Buildings;Visualization;Task analysis;Transformative play;Game based learning;Serious games;Human Trafficking;Role playing},doi={10.1109/CoG47356.2020.9231579},}
BirdSLAM: Monocular Multibody SLAM in Bird’s-Eye View
Swapnil Daga, Gokul B. Nair, Anirudh Ramesh, Rahul Sajnani, Junaid Ahmed Ansari, and K. Madhava Krishna
@inproceedings{Daga2020BirdSLAMMM,title={BirdSLAM: Monocular Multibody SLAM in Bird's-Eye View},author={Daga, Swapnil and Nair, Gokul B. and Ramesh, Anirudh and Sajnani, Rahul and Ansari, Junaid Ahmed and Krishna, K. Madhava},booktitle={VISIGRAPP},year={2021},url={https://api.semanticscholar.org/CorpusID:226964687}}
Exploring Empathy and a Range of Emotions Towards Protest Photographs
AadilMehdi J. Sanchawala, Adhithya Arun, Rahul Sajnani, Rishabh Chacko, and Kavita Vemuri
In Proceedings of the Annual Meeting of the Cognitive Science Society, Jun 2022
@inproceedings{Sanchawala2022ExploringEA,title={Exploring Empathy and a Range of Emotions Towards Protest Photographs},author={Sanchawala, AadilMehdi J. and Arun, Adhithya and Sajnani, Rahul and Chacko, Rishabh and Vemuri, Kavita},booktitle={Proceedings of the Annual Meeting of the Cognitive Science Society},year={2022},url={https://escholarship.org/uc/item/1rn4m0sh}}
 UniWALM: A Unified World-Action-Language Model for Embodied Robot ControlLEAP Workshop @ CoRL 2026; Under Review, 2027
 AppearancePointers: Fine-Grained Multi-Region Control with Appearance PointersUnder Review, 2027
 Sample-Efficient Reinforcement Learning for Policy Improvement via Flow-Reversed Action AnchorsUnder Review, 2027
 GeoDiffuser: Geometry-Based Image Editing with Diffusion ModelsIn Proceedings of the IEEE/CVF Winter Conference on Applications of Computer Vision (WACV)(Best Student Paper) , 2025
 GenHSI: Training-Free Controllable Generation of Human-Scene Interaction VideosIn Proceedings of the IEEE/CVF Winter Conference on Applications of Computer Vision (WACV), 2026
 Canonical Fields: Self-Supervised Learning of Pose-Canonicalized Neural FieldsIn Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)(Highlight) , Jun 2023
 LEGO-Net: Learning Regular Rearrangements of Objects in RoomsIn Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Jun 2023
 ConDor: Self-Supervised Canonicalization of 3D Pose for Partial ShapesIn Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Jun 2022
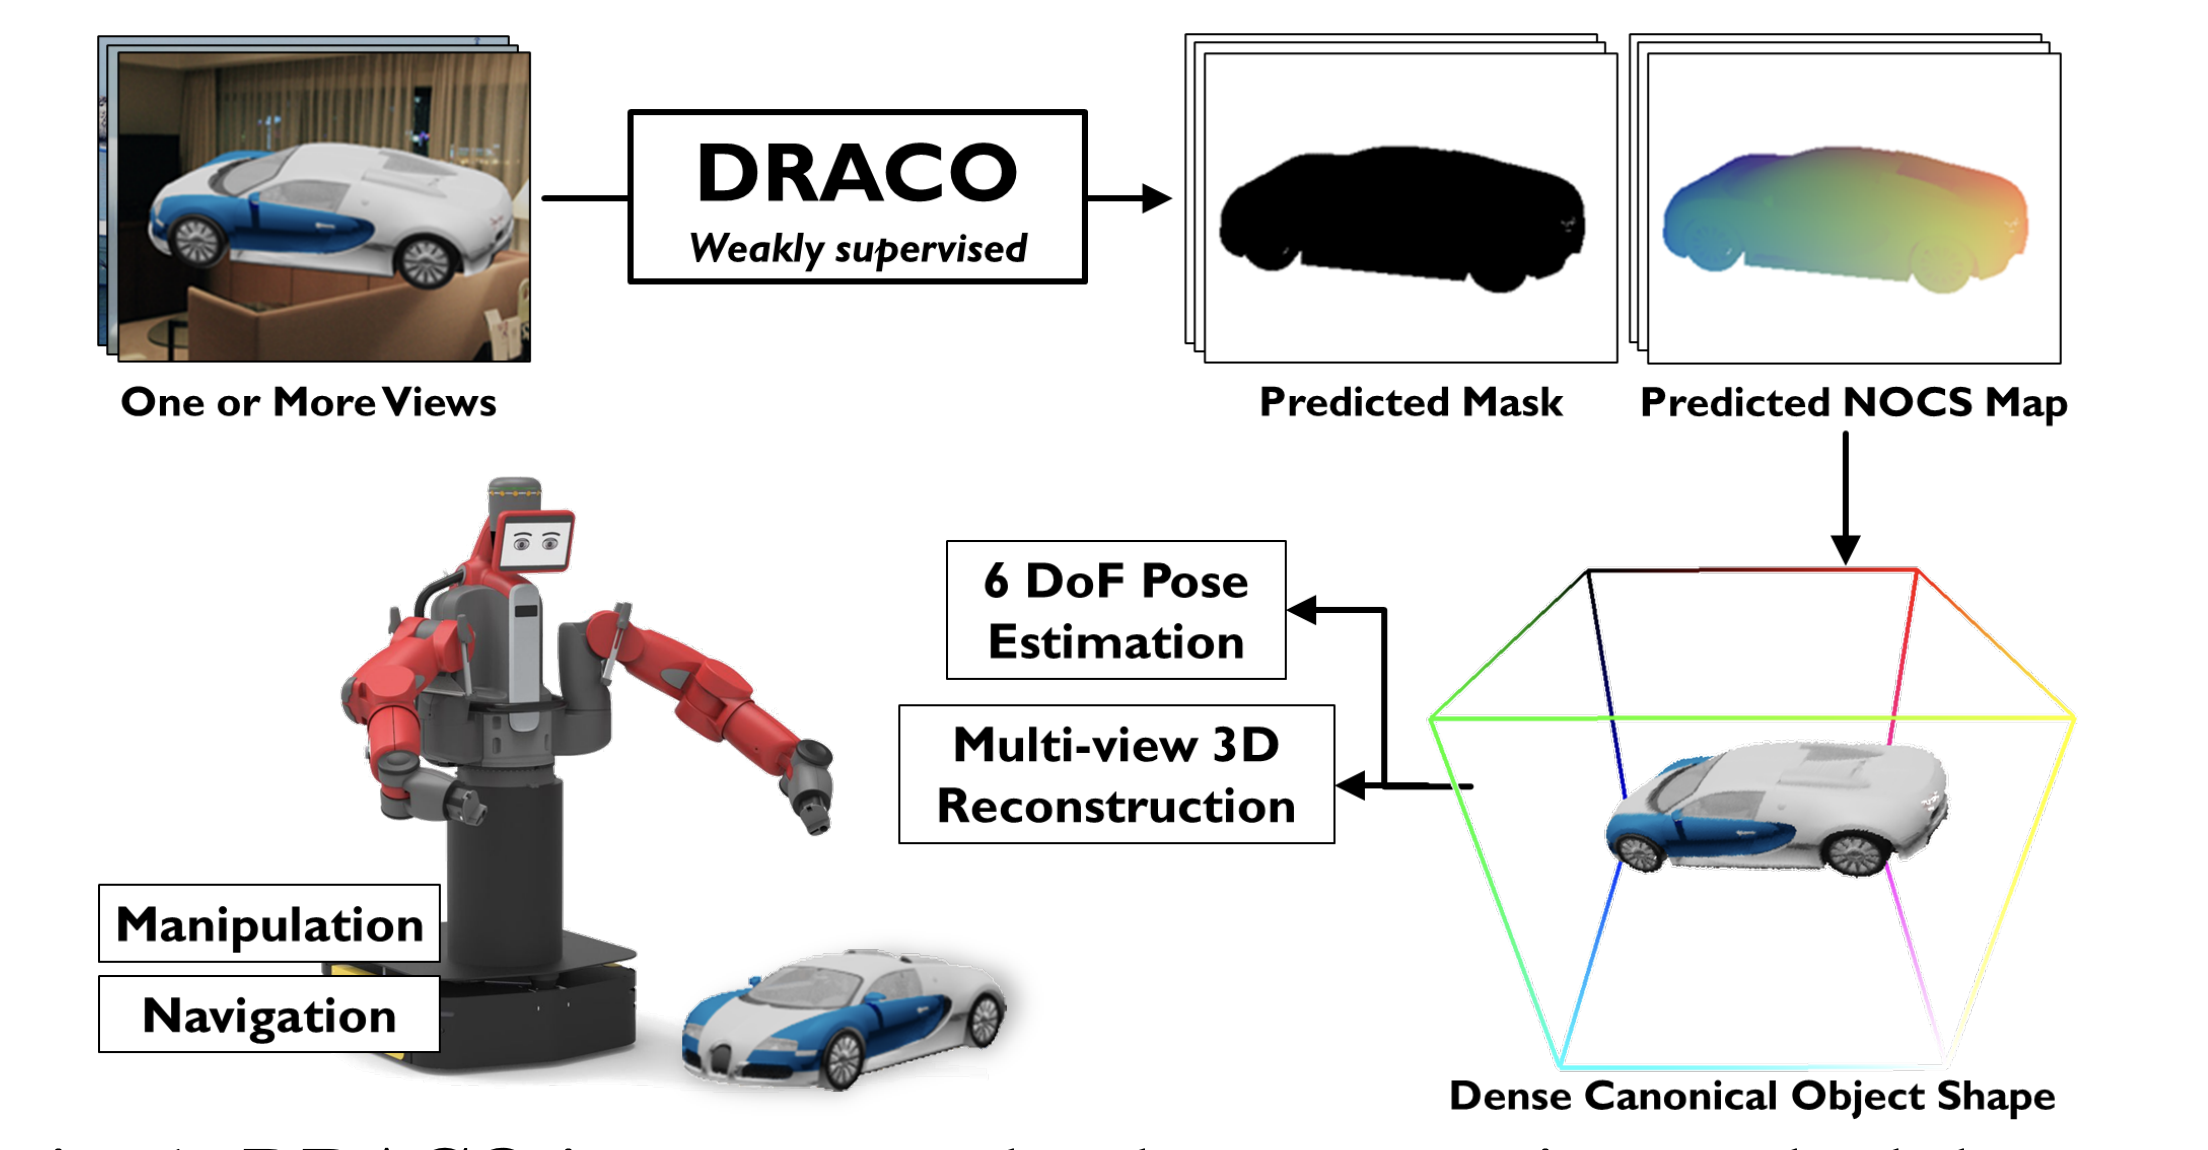 DRACO: Weakly Supervised Dense Reconstruction And Canonicalization of Objects2021 IEEE International Conference on Robotics and Automation (ICRA), Jun 2021